A location interview sounds clean in headphones until you open the recording on a larger system. Beneath the voice is a constant ventilation hiss, and a brief electronic beep crosses a sentence. Lowering the entire recording makes the problems quieter, but it also makes the speaker quieter. Removing only the unwanted sound requires a different kind of edit.
Spectral audio editing represents a recording by time and frequency so that persistent noise and isolated disturbances can be inspected separately from the desired signal. It can make speech easier to hear and a recording less distracting. It cannot reliably recreate sound that a microphone failed to capture, and aggressive processing can make a voice sound less natural than the original noise.
Why spectral audio editing needs more than a waveform
A waveform shows changes in signal amplitude over time. It helps an editor locate a pause, a sudden peak or a cut, but two sounds can overlap at one moment and produce a single combined waveform. A low electrical hum may be difficult to distinguish from speech merely by inspecting those amplitude peaks.
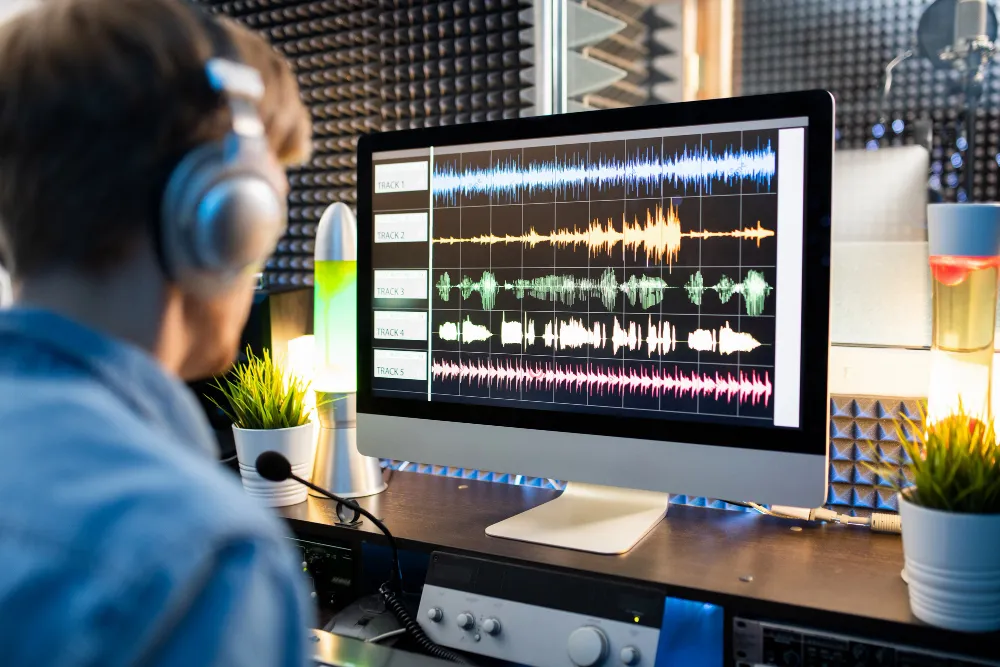
A spectrogram shows how frequency content changes over time. A sustained tonal disturbance may appear as a narrow band, while a brief impact can spread across many frequencies within a short interval. The brightness or color of a display usually reflects a scaled measure of spectral magnitude, not a direct reading of which source made the sound.
That distinction is important: a bright mark is evidence of signal energy, not proof that it is unwanted. A consonant, a musical overtone, and a machine tone can appear near each other on the display. The editor must listen and compare the pattern with the recording’s context before removing it.
The short-time Fourier transform builds the spectrogram
To reveal changing frequencies, a processor divides sampled audio into short, often overlapping frames. Each frame is windowed and transformed into a set of frequency components. This short-time Fourier transform, or STFT, preserves a sequence of local spectra rather than computing one spectrum for the entire recording.
Carnegie Mellon University’s explanation of the STFT shows why successive frames retain the timing of changing tones. A complete-recording Fourier transform can identify that several frequencies occurred, but it does not by itself say when they occurred. The time-frequency view adds that missing dimension.
Frame size involves a trade-off. Longer analysis windows can separate nearby sustained tones more clearly, but may smear a brief click across time. Shorter windows locate transients more precisely while providing coarser frequency separation. Changing a display scale or color palette makes a pattern easier to see; it does not itself change the recorded sound.
Noise patterns do not all have the same shape.
Steady broadband noise such as ventilation hiss appears across a wide range of frequencies and can persist through a recording. A mains-related hum occupies a narrow region and may have harmonics above its fundamental. An alarm beep may form a short horizontal streak, while a click often produces a thin vertical disturbance.
These appearances are useful clues but not universal signatures. A door slam, drum strike and microphone handling noise can all produce broadband energy for a short time. A musical note can resemble the steady tone of a machine. Recognizing the situation in which the recording was made is part of deciding which sound should remain.
An editor may isolate a brief interruption with a time-frequency selection, use a targeted filter on a persistent tone, and choose a broader noise estimator for steady hiss. Treating them all with the same global suppression setting can remove useful harmonics or leave obvious artifacts around each interruption.
How a noise print becomes an estimate, not a certainty
If a recording contains a pause with the same background ventilation noise but no speech, the software can use that interval to estimate the noise spectrum. The software measures how much energy is normally present in different frequency regions. It can then compare that estimate with frames that contain both speech and noise.
The quality of the estimate depends on the example. A pause that contains a chair scrape is not representative of steady hiss. A sample recorded before a fan changes speed may be a poor guide to the later recording. A noise-only interval is helpful because it reduces the chance that speech components will be classified as background noise.
Sometimes no truly clean noise segment exists. The processor may then update a model during likely pauses or infer noise statistics using other assumptions. Those approaches can be useful, but they make it more important to check whether quiet syllables and breaths survive. A noise profile is a statistical description, not a stored copy you can subtract from every moment.
Spectral subtraction reduces estimated noise energy.
Spectral subtraction works on a simplified model: an observed audio signal contains desired material mixed with an unwanted component. For each short frame, a processor estimates how much of the spectral magnitude or power may belong to noise and attenuates that contribution. The operation is adjusted so the remaining values do not become invalid or excessively unstable.
A NASA technical record on adaptive noise suppression describes estimating background noise during suitable speech intervals and varying spectral subtraction with signal conditions. It also discusses averaging over frames to reduce artifacts. The approach demonstrates a general signal-processing principle; it is not an independently established performance claim about any editing product.
Audio reconstruction then converts modified spectral data back to a waveform, using an inverse transform and frame recombination. Phase information and the way overlapping windows are combined affect the result. Removing colored patches from a display is therefore not equivalent to deleting a separable physical sound source; speech and noise can share the same spectral bins.
Targeted repair is different from processing an entire recording
For a single beep, the editor may select a small region around the tone and attenuate its energy while leaving the rest of the recording untouched. A localized repair can sometimes avoid the broad changes produced by treating a five-minute interview with one global noise model.
When speech overlaps the beep, however, the same region may contain useful vowels or consonants. Reducing its amplitude can leave a hole in the voice. Interpolation or patch-based repair may estimate the missing region from nearby material, but the estimate is a reconstruction, not a recovered, independent recording of what the speaker originally said.
The right choice depends on the interruption’s duration and how much it overlaps. A brief isolated tone is often easier to reduce than a loud alarm covering an entire sentence. The editor should compare the repair with the original at normal playback speed, not judge success solely by how clean the spectrogram looks.
Hum, hiss and intermittent noise need different treatments
A stable hum can sometimes be controlled with narrow frequency-selective filters, including a series aimed at harmonics. Very narrow filtering may leave the rest of the spectrum largely intact. But if a voice or instrument has important energy at the same frequencies, even a precise filter can change its character.
Broadband hiss is harder to isolate in that way because it overlaps much of the frequency range used by speech. Statistical attenuation can reduce its level across many bands, but stronger settings tend to remove low-level details as well. A passing vehicle or gust of wind creates an additional problem: its spectrum changes faster than a stationary noise estimate can track.
The practical workflow may combine a gentle broadband reduction with a local repair for a short intrusion. Each pass should address a specific audible problem. Applying several strong processors in succession can make it difficult to identify which stage introduced a new distortion.
Speech and music overlap with the noise being removed
Speech contains harmonics, rapid consonant bursts and transitions between vowels. Those features are not simply bright blocks that one threshold can separate from background sound. A weak consonant may be quieter than some noise bands, especially when the recording was made far from the microphone.
University laboratory research on speech enhancement emphasizes preserving changing speech components, including bursts and vowel transitions, while suppressing additive noise. The study supports considering temporal speech structure rather than treating every low-level spectral component as expendable.
Music introduces different difficulties. Cymbals and percussion are broadband and transient; sustained notes contain harmonics that may resemble electrical tones. Accredited-university research on broadband audio noise filtering examined protecting harmonic material and relaxing attenuation around percussion. An approach optimized for spoken dialogue should not automatically be assumed suitable for every musical recording.
Musical noise is an artifact, not music left in the recording
After aggressive suppression, a recording can develop faint chirps, watery tones or fluctuating metallic sounds that were not present in the source. These artifacts are often called musical noise. They can arise when unstable residual spectral components remain in scattered time-frequency regions and change sharply from one frame to another.
Increasing the amount of subtraction is not a universal fix. It may deepen the gaps between surviving components and make the artifacts more noticeable. Smoothing, a controlled residual noise floor, or a more appropriate estimate can reduce some of that instability, though each also affects audible detail.
A sensible target is often a lower but still natural background rather than an absolutely silent spectrogram. Listeners can tolerate consistent room ambience more easily than repeated chirps or a voice whose breaths vanish between words. The required degree of cleanup depends on the material and its intended use.
Noise reduction cannot reverse every recording failure
Reverberation is sound reflected from a room and mixed with the direct voice over time. It differs from an independent stationary hiss, so subtracting a noise profile does not simply remove the room response. Dereverberation methods attempt to estimate or reduce those reflections, with varying success and the risk of altering speech.
Clipped digital peaks are another separate problem. Once a recorder has replaced part of a waveform with a limiting value, the original peak shape is no longer present in the saved signal. A repair algorithm can estimate a plausible contour, but it cannot verify that the estimate is what the microphone would have captured without overload.
Address distance, microphone placement, and room acoustics during recording when possible. Post-production can improve compromised material, but it cannot substitute for a quiet location, adequate signal level and recording a short sample of the surrounding ambience.
Automated denoising still needs a listening test.
Some modern processors use learned patterns rather than only a simple noise spectrum. They may distinguish likely speech from background sounds in difficult recordings. That model can help when no clean noise-only sample exists, but the output is an estimate shaped by training and input conditions.
Processed voice can become clearer while losing natural breaths, consonant detail, or the character of the recording space. Perceived cleanliness is not the same as faithful reconstruction. For evidence-sensitive material, document edits and retain the untouched source so a reviewer can compare what was recorded with what was inferred.
The difference also matters to tests of speech-driven software. A denoised clip might become easier for one recognition system to transcribe while sounding less natural to a human. Evaluation should use the actual downstream task and include the unprocessed recording as a reference.
Preserving the original recording is part of quality control
Before editing, retain an unchanged source copy and record its sample rate, bit depth, channel arrangement and provenance where available. Work on a separate version and keep track of processing order. A later editor should be able to identify what was removed and compare the result with the source.
The Library of Congress’s audio format guidance favors well-documented, high-quality material and suitable uncompressed or lossless delivery where available. Its publication guidance does not claim that an edited copy substitutes for an original recording. Long-term storage and listening access are different decisions from choosing how much noise to remove.
Project files can depend on source audio, edit decisions and render settings. A related guide to creative asset synchronization explains how linked media and revisions can drift apart across tools. That problem applies to sound restoration too: an exported cleaned track isn’t enough if you can’t reconstruct the source and editable decisions.
Finally, listen to the decoded output on more than one playback system and at a sensible level. Compare speech intelligibility, transients, remaining background sound and the presence of new artifacts. Spectral audio editing succeeds when it reduces a specific interference without disguising the recording’s limitations or erasing the sound that matters.