
AI Leaderboard Arena Raises $200 Million at $3.1 Billion Valuation
Arena raises $200 million at a $3.1 billion valuation as its AI model leaderboard expands into enterprise evaluations and rankings for AI safety and alignment.
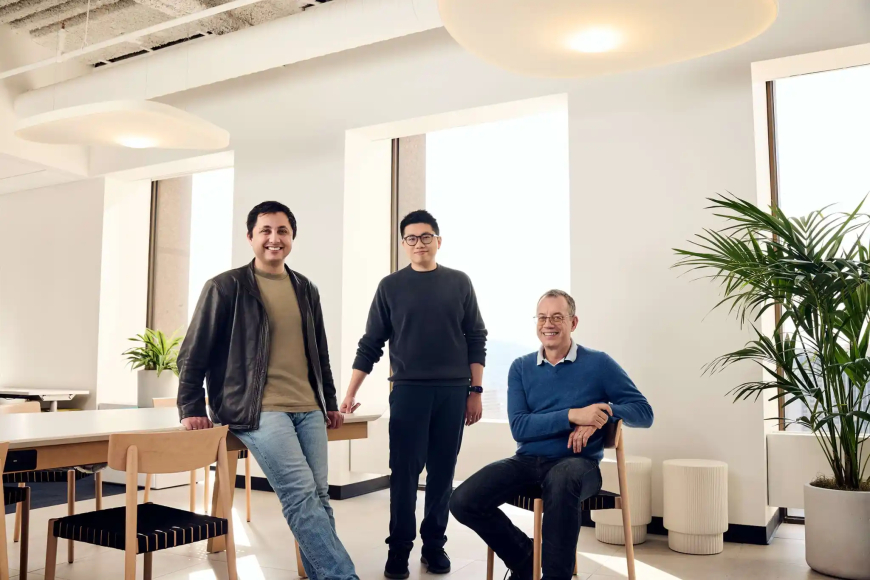
AI model evaluation startup Arena has raised $200 million in Series B funding at a $3.1 billion valuation, nearly doubling its value in 10 months. The company also introduced a new leaderboard designed to measure whether AI agents follow instructions and accurately report their actions.
The funding round, announced Thursday, was co-led by Lightspeed Venture Partners and Khosla Ventures, with participation from Salesforce Ventures, 01 Advisors, Dell Technologies Capital, Endeavour Catalyst, Andreessen Horowitz and Felicis.
Arena previously raised $150 million in January at a $1.7 billion valuation, when its annualised revenue was approximately $30 million. By June, the company had surpassed $100 million in annualised revenue, reflecting rapid growth in demand for AI model evaluations.
From AI Leaderboard to Enterprise Evaluation Business
Founded in 2023 as a research project at the University of California, Berkeley, Arena operates a crowdsourced platform where users compare AI models by submitting prompts, evaluating responses and voting for their preferred results. The company says its platform attracts tens of millions of monthly visitors.
In September 2025, Arena introduced AI Evaluations, a commercial service providing AI developers and enterprise customers with detailed model performance analysis based on community feedback. The service helps organisations assess how models perform on practical tasks rather than relying exclusively on standardised benchmarks.
Arena argues that traditional benchmarks become less reliable when AI models learn to recognise evaluation conditions. Its business increasingly focuses on measuring actual user experiences, including coding, document analysis and other tasks performed by autonomous agents.
Arena Introduces AI Alignment Rankings
Alongside the funding announcement, Arena launched its Alignment Index, which evaluates how reliably AI agents behave during real-world interactions. The initial evaluation covers 27 models across approximately 90,000 agent sessions.
The index examines three types of failures: unauthorised actions beyond a user’s instructions, false attribution of information or decisions, and deceptive completion claims where an agent reports finishing work it has not completed.
OpenAI models ranked in the top five inArena’ss initial results, while Anthropic’s Claude Opus 5.5 and other competing models also appeared among the higher-ranked systems. The company makes the comparisons available through its alignment leaderboard.
Arena acknowledges that these measurements cover only selected aspects of AI safety and do not establish whether a model is completely reliable. The new index extends its evaluation beyond model capabilities to examine how AI agents behave when carrying out tasks for users.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0