
GPT-6.1 Sol and Claude Sonnet 5.5 Make Frontier AI Cheaper — With Important Tradeoffs
GPT-6.1 Sol and Claude Sonnet 5.5 bring near-flagship AI performance to lower-cost coding and agent workloads, but token usage and reasoning effort can dramatically change the real cost.
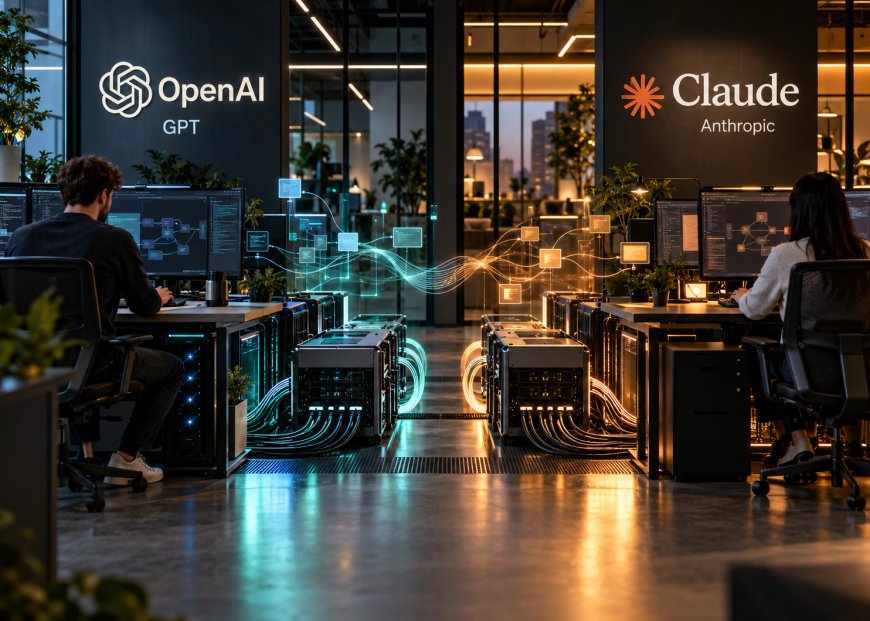
The most important AI releases this fall may not be the models setting a new absolute performance record. They may be the ones bringing yesterday’s frontier performance down to prices developers can use every day.
OpenAI’s GPT-6.1 Sol and Anthropic’s Claude Sonnet 5.5 arrived within a day of each other at the end of September, and both follow essentially the same strategy. Neither company is presenting its new model as the most capable system it has ever built. Instead, OpenAI is pushing Sol closer to its much more expensive GPT-6 Astra, while Anthropic is bringing Sonnet surprisingly close to Claude Opus 5.5.
That makes the comparison less about which model wins a benchmark and more about something that matters increasingly in production AI: how much useful work a developer gets for every dollar and every second of compute.
GPT-6.1 Sol Replaced Its Predecessor Almost Immediately
OpenAI released GPT-6.1 Sol on September 29, only a week after GPT-6 Sol. The turnaround is unusually fast even by current AI-industry standards. It makes the original Sol look more like a short-lived waypoint than a model intended to anchor OpenAI’s lineup for long.
OpenAI describes GPT-6.1 Sol as a model for complex coding, computer use and professional work that approaches Astra-level capability at substantially lower cost. The standard API price is $2 per million input tokens and $10 per million output tokens, identical to GPT-6 Sol. Cached input, however, has fallen from $0.20 to $0.10 per million tokens, making repeated-context workloads such as coding agents and long-running enterprise systems slightly cheaper.
The model has a 1.05-million-token context window and supports up to 128,000 output tokens. Reasoning effort can be adjusted from low through medium, high, xhigh and max, with medium serving as the default.
Those specifications make GPT-6.1 Sol considerably cheaper than GPT-6 Astra, which costs $10 per million input tokens and $50 per million output tokens at standard API rates. In raw token pricing, Sol is one-fifth the price.
Independent testing suggests OpenAI has preserved much of Astra’s capability while dramatically cutting costs. Artificial Analysis reported that GPT-6.1 Sol finished only one point behind GPT-6 Astra on its Intelligence Index while costing less than one-quarter as much per task in its evaluation. The new model also improved four points over the original GPT-6 Sol on that index.
That does not make Astra obsolete. OpenAI still recommends its flagship for the hardest scientific and professional work. Sol is better understood as the model developers might use when a task needs serious reasoning but occurs too frequently to justify flagship pricing.
Claude Sonnet 5.5 Is Chasing Opus From Below
Anthropic is making a remarkably similar move with Claude Sonnet 5.5.
Released September 28, Sonnet 5.5 sits below Opus 5.5 in Anthropic’s lineup but closes much of the capability gap. Anthropic says it is more than 30% faster than Sonnet 5 and can cost up to 30% less per task because it often completes work using fewer tokens.
The API remains priced at $2 per million input tokens and $10 per million output tokens, precisely the same headline rates as GPT-6.1 Sol. Sonnet 5.5 also includes a one-million-token context window and up to 128,000 output tokens, while cached input costs $0.20 per million tokens.
On Anthropic’s own evaluations, the new Sonnet lands surprisingly close to Opus 5.5. It scored 70.6% on Terminal-Bench 4.0, compared with 66.4% for Opus 5.5 in Anthropic’s published results, and finished only two points behind Opus on GDPval-AA, an evaluation intended to measure professional knowledge work.
Independent testing paints a similar overall picture, but with an important warning about efficiency. Artificial Analysis placed Sonnet 5.5 just two points behind Opus 5.5 on its Intelligence Index when both were pushed toward their strongest settings. The problem is that Sonnet used an unusually large number of reasoning and output tokens to reach that score.
At maximum effort, Artificial Analysis measured roughly 194,000 output tokens per task and an average cost of about $7.62 on its evaluation workload. At medium effort, cost fell to roughly $0.59 per task, while output usage dropped to around 19,000 tokens.
That difference is enormous and explains why comparing models purely by per-token prices can be misleading.
Cheap Tokens Do Not Always Mean a Cheap Task
The emerging lesson from both releases is that AI pricing is becoming harder to understand from a simple input-and-output rate.
A model priced at $2 and $10 per million tokens can still become expensive if it reasons for a long time, generates huge internal trajectories or repeatedly calls tools before completing a task. Another model with higher token rates may finish the same job using fewer tokens and ultimately cost less.
Reasoning effort makes this even more complicated. More thinking does not guarantee proportionally better answers.
Artificial Analysis found that moving Sonnet 5.5 from medium to high effort increased its measured cost per task from roughly $0.59 to $1.08, while maximum effort pushed that figure above $7. The performance gains were real, but the relationship between intelligence and spending was far from linear.
Anthropic itself has documented cases where greater effort can actually hurt benchmark performance. On one software-engineering evaluation, Sonnet 5.5 performed worse at maximum effort because it became more aggressive about reviewing and changing code, sometimes producing additional modifications outside the benchmark’s intended scope.
That is a useful reminder for developers tempted to move every workload to the highest possible reasoning setting. More compute can make a model more thorough, but it can also make it slower, more expensive and occasionally too ambitious for a tightly defined task.
The sensible approach is increasingly to choose the lowest effort level that reliably meets the application’s quality threshold.
Sonnet 5.5 and GPT-6.1 Sol Are Targeting Similar Jobs
The overlap between the two models is striking. Both target coding, agents, a nd professional knowledge work, and both are priced at $2 for input and $10 for output.
Claude Sonnet 5.5 is particularly interesting for developers already working inside Claude Code or building workflows where Anthropic’s agentic coding behaviour is valuable. Anthropic positions the model for bug fixing, documents, spreadsheets, slides, software development and other well-scoped work where Opus-level judgment may not be necessary.
GPT-6.1 Sol has a slightly broader positioning around coding, computer use and professional tasks. It also supports computer-use tooling through OpenAI’s API ecosystem and gained beta multi-agent functionality at launch, allowing one Sol request to delegate work to subagents.
Neither model therefore replaces its company’s flagship. Opus 5.5 remains Anthropic’s stronger choice for difficult work requiring more careful judgment, while Astra remains OpenAI’s recommendation when maximum capability matters more than cost.
What has changed is how often developers may actually need those flagships.
The AI Race Is Shifting Toward Cost per Useful Result
For the past several years, AI competition has centred on which laboratory has the smartest model. GPT-6.1 Sol and Claude Sonnet 5.5 suggest that another race is becoming just as important.
Once models cross a certain capability threshold, businesses care about whether they can afford to run them thousands or millions of times.
A model that is marginally less capable but costs dramatically less can be far more valuable inside a customer-support operation, coding platform, research workflow or autonomous agent. Likewise, a cheaper model that burns through far more tokens than expected may not deliver the savings advertised by its headline API rate.
That is why the most useful comparison between GPT-6.1 Sol and Claude Sonnet 5.5 cannot be reduced to a leaderboard. Developers need to test their own workloads, at the effort levels they will actually use, and measure successful-task cost rather than token price alone.
Neither release fundamentally changes the ceiling of frontier AI. What they do is make that capability more economically practical.
That may prove just as consequential. The next stage of the model race is not only about making AI smarter. It is about making intelligence cheap enough that companies can afford to use it everywhere.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0